
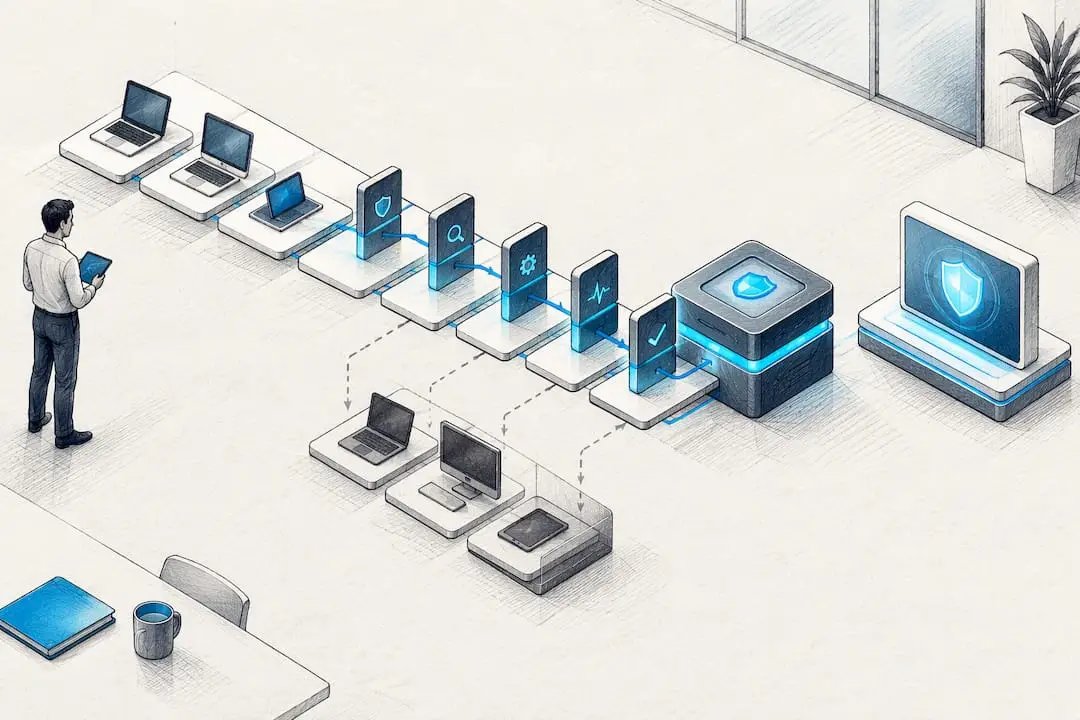
EDR deployment is the staged process of installing sensors on endpoints, connecting their telemetry to your detection stack, and tuning detection and response until every device is visible and actionable. The single most important first move is not buying a licence or picking a vendor. It is completing an endpoint inventory and choosing your onboarding path, automatic rollout via Intune for Windows fleets, manual installation for macOS, Linux and mobile. SIEM integration and role-based access control come next, but they only work once that foundation is in place.
TL;DR:
- Completing an endpoint inventory is the critical first step before deploying EDR, helping identify device OS, high-value assets, and network chokepoints.
- Deployment success relies on proper licensing, role assignments, and staged rollout, with automation favored on Windows and manual steps needed for macOS, Linux, and mobile devices.
- Regularly monitoring sensor health, coverage rate, and telemetry quality ensures false positives are minimized, and detection effectiveness remains high over time.
- Integrating EDR telemetry with SIEM, DNS, and network flow data enhances detection accuracy, with sequencing these integrations to optimize cost and value.
- Ongoing tuning, strict access controls for management consoles, and thorough incident playbook testing are vital to maintaining effective detection and response capabilities.
Table of Contents
- What EDR does and where it sits in your security stack
- Key benefits and success metrics for an EDR deployment
- Pre-deployment assessment: inventory, risks, network and licensing checklist
- Choosing your deployment model and architecture (agents, telemetry, retention)
- Platform-specific onboarding practical steps: Windows, macOS, Linux and mobile
- Pilot and phased rollout template: who to include, how to measure and when to expand
- Configuration, tuning and alert management to improve signal and reduce noise
- Integrations and telemetry: SIEM, DNS and network flow monitoring, threat feeds
- Operational readiness: RBAC, protecting deployment consoles and incident playbooks
- Monitoring, reporting and ongoing maintenance
- Common pitfalls and troubleshooting checklist
- Lancast perspective: how we deliver managed EDR outcomes
- How Lancast can help with your EDR deployment
- Sources
- FAQ
What EDR does and where it sits in your security stack
Endpoint detection and response gives you continuous visibility into what is happening on every laptop, server and workstation you manage. Microsoft describes EDR as a system built on continuous telemetry collection, behavioural analytics, investigation tooling and automated containment, and it is explicit that this is not the same thing as traditional antivirus. Antivirus and endpoint protection platforms (EPP) block known threats at the point of execution. EDR assumes some threats will get past that layer, and it records everything that happens afterwards so you can hunt, investigate and contain.
That distinction matters when you are deciding where EDR fits alongside your existing tools. A SIEM aggregates logs from across your estate, including EDR telemetry, but it rarely sees process-level endpoint behaviour with the same granularity. EDR fills that gap. It also feeds the SIEM, which is why the two are complementary rather than competing purchases.
You have three broad models to choose from when planning endpoint detection response for your organisation:
- Self-managed EDR — your own security team owns tuning, triage and response, giving full control but demanding in-house skills and 24/7 coverage.
- Managed EDR (MDR) — a provider operates detection and response on your behalf, useful where staffing or out-of-hours coverage is thin.
- Hybrid — your team retains ownership of policy and escalation while a partner handles overnight monitoring or specialist triage.
The right choice depends less on budget alone and more on whether you can staff a security operations function around the clock. A ten-person IT team supporting a 200-seat business rarely can do so, which is why hybrid and managed arrangements dominate the mid-market.
Key benefits and success metrics for an EDR deployment
The case for EDR rests on speed. Attackers who compromise an endpoint typically have a window before they move laterally or exfiltrate data, and EDR’s job is to shrink that window from days to hours. Automated containment, isolating a host, killing a process, blocking a network connection, buys your analysts time without waiting for a human to act first.
Once deployed, you should be tracking a small set of metrics rather than drowning in dashboards:
- Mean time to detect (MTTD) — how long between compromise and alert.
- Mean time to respond (MTTR) — how long between alert and containment.
- Coverage rate — how many endpoints report healthy telemetry.
- Sensor health — active versus inactive or impaired agents across the fleet.
Pro Tip: Coverage rate is the metric most teams ignore until an incident exposes a gap. Review it regularly, especially in early weeks after rollout when device churn is highest.
ENISA’s proactive detection guidance points out that endpoint monitoring works best when paired with SIEM integration and network-level monitoring, and that resource and expertise shortages are the most common reason organisations fall short of that baseline. Set your metrics with that constraint in mind. A smaller team measuring three things consistently beats a larger one measuring twelve badly.
Pre-deployment assessment: inventory, risks, network and licensing checklist
Every EDR rollout that goes badly starts the same way: someone skipped the inventory. Before you touch a licence key, you need an accurate picture of what you are protecting and what stands in the way.
- Catalogue every endpoint and its operating system. Include servers, workstations, laptops and any unmanaged or bring-your-own devices, since these are usually where onboarding fails first.
- Identify high-value assets and segmentation boundaries. Domain controllers, finance systems and anything holding regulated data should be prioritised in the first onboarding wave, not the last.
- Map network chokepoints. SSL/TLS inspection appliances and proxies are a frequent, avoidable cause of failed agent communication, and vendor technical guidance recommends allowlisting agent traffic or bypassing inspection for those flows before deployment, not after telemetry stops arriving.
- Confirm licensing and admin roles. For Microsoft-managed environments, you will need Defender for Endpoint Plan 1 or 2, or an M365 E5, A5 or G5 licence, along with an Endpoint Security Manager role or equivalent assigned before you attempt onboarding.
- Set a realistic timeline and staffing plan. A mid-sized estate of a few hundred endpoints typically needs weeks, not days, once pilot, phased rollout and tuning are factored in.
Pro Tip: Run the licensing and RBAC check before the network survey, not after. Teams that discover a missing role assignment mid-rollout lose days waiting on approval chains that could have been cleared in advance.
Budget conversations go smoother once this checklist is complete, because you can point to specific gaps, an unpatched proxy, a missing licence tier, rather than asking for a vague contingency.
Choosing your deployment model and architecture (agents, telemetry, retention)
Agent-based EDR remains the standard for genuine visibility. Agentless approaches, which rely on network sensors or API polling, reduce installation overhead but see far less of what happens inside a process, which limits investigation depth when something does go wrong. Most organisations running production EDR use agents on every managed endpoint and reserve agentless monitoring for devices that genuinely cannot host one, such as certain IoT or legacy systems.
Telemetry storage location affects how useful your data is months later:
- Cloud-hosted telemetry scales easily and usually ships with built-in retention tiers, but check what happens to data once the retention window closes.
- On-premises storage gives full control over retention and compliance but adds infrastructure and backup responsibilities your team must own.
- Retention length directly shapes investigation quality. Short windows save cost but can leave you unable to reconstruct an incident that unfolded over several weeks.
The self-managed versus managed EDR decision comes back to skills and cost. A self-managed setup demands analysts trained in triage and threat hunting around the clock, while managed EDR shifts that burden to a provider under a service level agreement. Neither is universally correct. What does matter, regardless of model, is that EDR integrates with your identity provider and conditional access policies, so a detected compromise can trigger an automatic access restriction rather than waiting for a manual ticket.
Platform-specific onboarding practical steps: Windows, macOS, Linux and mobile
Windows onboarding is the most automated path available, and it is worth using that automation rather than manual installers wherever your estate allows it.
- Confirm licensing and roles first. You need the correct Defender for Endpoint or M365 licence tier and the Endpoint Security Manager role assigned in Intune before you begin.
- Enable the service-to-service connector between Defender for Endpoint and Intune. Microsoft’s Intune documentation walks through this connection step by step, and it is the fastest route to automatic onboarding for Windows fleets.
- Download and deploy the onboarding package, or use Configuration Manager tenant attach if you are running a hybrid ConfigMgr and Intune environment.
- Deploy preconfigured EDR policies to target device groups rather than pushing to every endpoint simultaneously.
- Check the EDR Onboarding Status report inside Intune to confirm devices are reporting as active rather than inactive or impaired.
macOS and Linux do not benefit from the same level of automation, so manual steps matter more there.
- Install the platform-specific package through your existing software distribution tool (Jamf for macOS, or your Linux configuration management system).
- Verify entitlement and kernel extension approvals on macOS, since unapproved system extensions will silently block sensor functionality.
- Confirm the Linux distribution and kernel version are on the vendor’s supported list before mass deployment, since unsupported kernels are a common source of failed telemetry.
- Test on a small representative sample of each OS variant before wider rollout, particularly across different Linux distributions running in the same estate.
Mobile devices raise a different set of questions. Full EDR agents are less common on iOS and Android, so most organisations rely on mobile device management (MDM) enrolment combined with the platform’s built-in threat defence integrations rather than a dedicated sensor. Confirm your MDM policy enforces enrolment before a device gets any corporate data access, and treat unmanaged personal devices as a visibility gap you note rather than pretend to have solved.
Across every platform, the onboarding status and sensor health reports are your verification tool of choice. A device that installed the agent but shows as impaired is not protected, regardless of what the deployment log says.
Pilot and phased rollout template: who to include, how to measure and when to expand
A pilot exists to surface problems while the blast radius is small. Skipping it to save some time is a common reason full rollouts stall midway through.
- Choose a representative pilot group of several devices, mixing operating systems, hardware age and user roles rather than picking the easiest machines in the building.
- Include at least one high-value or sensitive system in the pilot, since it is better to find a configuration conflict there early than after wider rollout.
- Run the pilot for two to four weeks, long enough to capture a normal patch cycle and typical user behaviour patterns.
- Validate telemetry daily during week one. Check that sensors report active status, that alerts generate correctly against test scenarios, and that no unexpected performance complaints surface.
- Set acceptance criteria before expanding. A reasonable bar is 95%+ sensor health, no unresolved false-positive storms and confirmed SIEM ingestion.
- Define rollback triggers in advance. Repeated agent crashes, unresolved performance degradation on critical systems or telemetry gaps lasting more than 24 hours should each trigger a pause, not a workaround pushed live under pressure.
- Schedule phased expansion around existing maintenance windows rather than adding a new change cycle your operations team has to learn separately.
Tuning should not stop once the pilot ends. Treat the acceptance criteria as a recurring check at each phase boundary, not a one-off gate you pass and forget.
Configuration, tuning and alert management to improve signal and reduce noise
Alert fatigue kills EDR programmes faster than any technical failure. Analysts who wade through hundreds of low-value alerts a day start ignoring the queue, and that is when the one genuine incident slips past unnoticed.
- Set collection levels deliberately. Full telemetry sampling gives the richest investigation data but generates the most volume; a reduced sampling rate on low-risk device groups can cut noise without sacrificing coverage on critical assets.
- Use exclusions sparingly and document every one. Every exclusion is a blind spot, so tie each one to a specific business justification and review the list quarterly.
- Decide which alerts trigger automated containment versus analyst review. High-confidence indicators, such as known ransomware behaviour patterns, are good candidates for automatic isolation; ambiguous alerts belong in a human queue.
- Plan forensic retention separately from general telemetry retention. An incident under active investigation may need data held well beyond your standard retention policy.
Vendor-neutral guidance consistently frames EDR effectiveness as a cycle: deploy, measure telemetry quality, tune detections, then repeat. Treat tuning as a monthly discipline, not a one-time setup task.
Pro Tip: Review your top ten most frequent alert types every month. If the same low-value alert keeps firing, that is a tuning failure, not a detection success, however satisfying the alert count looks in a report.
Integrations and telemetry: SIEM, DNS and network flow monitoring, threat feeds
EDR telemetry becomes far more valuable once it stops living in isolation. Forwarding process execution, network connection and file modification events to your SIEM lets analysts correlate endpoint behaviour with server and network logs, catching patterns no single tool would flag alone.
- Forward high-fidelity EDR events to your SIEM, prioritising process creation, network connections and credential access alerts over low-value informational logs.
- Add DNS and network flow monitoring as a low-overhead complement. ENISA highlights that smaller teams gain disproportionate value from DNS and flow data because it costs far less to collect and store than full packet capture.
- Prioritise threat intelligence feeds that match your sector, and where relevant, engage with an information sharing and analysis centre (ISAC) for context specific to your industry.
- Treat harmonised telemetry as a false-positive reduction tool, not just a detection enhancement. Correlated data across sources filters out noise that any single feed would flag on its own.
Budget-constrained teams should sequence this work: SIEM forwarding first, DNS and flow monitoring second, curated threat feeds third. Each layer adds value, but the first two cost the least and close the biggest gaps.
Operational readiness: RBAC, protecting deployment consoles and incident playbooks
Your EDR management console is itself a target, and treating it as just another admin tool is a mistake attackers count on. MITRE ATT&CK’s guidance on software deployment tools warns that consoles like Intune, ConfigMgr and similar orchestration platforms are high-value targets precisely because compromising one gives an attacker a legitimate channel to push code across an entire estate.
- Enforce least-privilege RBAC with dedicated onboarding roles rather than broad administrator access for anyone who touches the console.
- Monitor the console itself for anomalous activity, following detection guidance for deployment tool abuse, which recommends watching for script execution from unusual accounts, deployments run outside scheduled maintenance windows, and mismatches between admin group membership and the org IDs performing changes.
- Store incident playbooks outside the systems they cover, so a compromised endpoint or console does not also take out your response documentation.
- Test playbooks at least twice a year through tabletop exercises, not just when a live incident forces the first read-through.
ENISA’s incident management guidance notes that outsourcing parts of incident management is reasonable, but recommends keeping sensitive monitoring and escalation decisions under close internal oversight rather than handing the whole function away.
Monitoring, reporting and ongoing maintenance
An EDR deployment does not finish at go-live. It settles into a recurring rhythm of checks that either catch drift early or let it accumulate into a blind spot nobody notices until an audit or an incident.
- Check onboarding status and sensor health daily, flagging any device that has moved from active to inactive or impaired.
- Schedule sensor and policy updates on a fixed cadence, testing each update against a small device group before pushing it fleet-wide.
- Run periodic validation exercises, including simulated incidents and purple team engagements, to confirm detections still fire as configured after months of tuning changes.
- Review telemetry retention against your compliance obligations at least annually, since data protection requirements can shift faster than your original retention policy anticipated.
Sensor health reporting, again drawn from the EDR Onboarding Status report for Microsoft-managed environments, should be a standing item in your weekly security operations review, not an afterthought pulled up only when something breaks.
Common pitfalls and troubleshooting checklist
Most EDR deployment failures trace back to a handful of repeat offenders, and knowing them in advance saves days of diagnosis.
- SSL/TLS inspection blocking agent traffic. If sensors show as impaired shortly after network changes, allowlist the agent’s management endpoints or bypass inspection for that traffic, as vendor guidance recommends.
- Telemetry spikes overwhelming storage or bandwidth. Apply throttling or adjust sampling on lower-risk device groups rather than letting the pipeline back up silently.
- Licence or role misconfiguration. Revisit the RBAC and licensing checklist from your pre-deployment assessment; a missing role assignment is often the real cause behind a “failed onboarding” ticket.
- Alert storms after a policy change. Apply temporary containment thresholds and triage the top alert sources immediately rather than letting the whole team drown in the queue for days.
Pro Tip: Keep a running log of every onboarding failure and its root cause during the first month. Patterns emerge fast, usually clustering around two or three network segments or device images, and fixing the image beats fixing devices one at a time.
Lancast perspective: how we deliver managed EDR outcomes
We run EDR engagements the same way every time: assessment first, pilot second, managed rollout third, then ongoing tuning as a permanent fixture rather than a phase that ends. That order exists because we have seen what happens when it gets reversed, teams buy licences before they understand their own estate, and the pilot becomes a scramble rather than a controlled test.
Continuous monitoring sits at the centre of how we operate deployments for clients, paired with our Microsoft Cloud Service Provider relationship for organisations onboarding through Intune and Defender. That combination lets us catch sensor health problems and onboarding gaps before they become client-facing incidents, rather than after. We treat tuning as a monthly discipline because alert fatigue is what quietly undermines a technically sound deployment months after everyone has stopped paying attention to it.
— Carl
How Lancast can help with your EDR deployment
Lancast is the practical alternative to building an around-the-clock security operations function from scratch, we run the assessment, pilot and phased rollout for you, then keep tuning it long after go-live. Managed services cover onboarding across Windows, macOS, Linux and mobile estates, ongoing sensor health monitoring, and incident response when something does trigger, supported by partnerships with leading technology vendors.
If you are weighing up a managed provider, ask three questions before you sign anything: who owns tuning after month one, how sensor health is reported to you, and what the escalation path looks like at 2am on a Sunday. Those answers separate a genuine managed EDR partner from a reseller who disappears after installation.
Our Silver, Gold and Platinum Support plans are built around exactly that ongoing relationship, and our security services cover penetration testing and vulnerability management alongside deployment work, so your EDR rollout sits inside a wider risk picture rather than standing alone. Get in touch to talk through where your estate stands today and what a phased rollout would look like for your team.
Sources
- Deploy endpoint detection and response policy with Intune – Microsoft Learn
- Software Deployment Tools (T1072) — MITRE ATT&CK
- ENISA report — Proactive detection: gap analysis, good practice and recommendations
- Proxy and SSL/TLS considerations for EDR agent traffic — vendor technical guidance
FAQ
What does EDR stand for?
EDR stands for endpoint detection and response, a category of security tooling that continuously monitors endpoints for suspicious behaviour and supports investigation and containment. It goes beyond traditional antivirus by recording detailed telemetry rather than only blocking known threats.
Is EDR the same as SIEM?
No. EDR focuses on endpoint-level telemetry, detection and response, while a SIEM aggregates and correlates logs across your entire environment, including EDR data. They work together rather than replacing one another, with EDR typically feeding events into the SIEM for broader correlation.
What is an example of an EDR?
Microsoft Defender for Endpoint is a widely deployed EDR platform, particularly in organisations already using Intune or Microsoft 365 for device management. Other established platforms exist across the market, but the underlying capabilities, continuous telemetry, behavioural detection and automated response, remain consistent across the category.
Is Microsoft Defender an EDR?
Yes, Microsoft Defender for Endpoint is a full EDR solution when licensed under Plan 1, Plan 2, or an M365 E5, A5 or G5 tier, not just antivirus. It supports automatic onboarding through Intune, which is one of the more straightforward deployment paths available for Windows-heavy estates.
How much does managed EDR deployment cost with Lancast?
Pricing depends on estate size, platform mix and the level of ongoing management required, so it is not published as a flat rate. Current details are available directly through Lancast’s managed services page, where you can request a scoped quote for your organisation.